
Loading…
11 September 2026
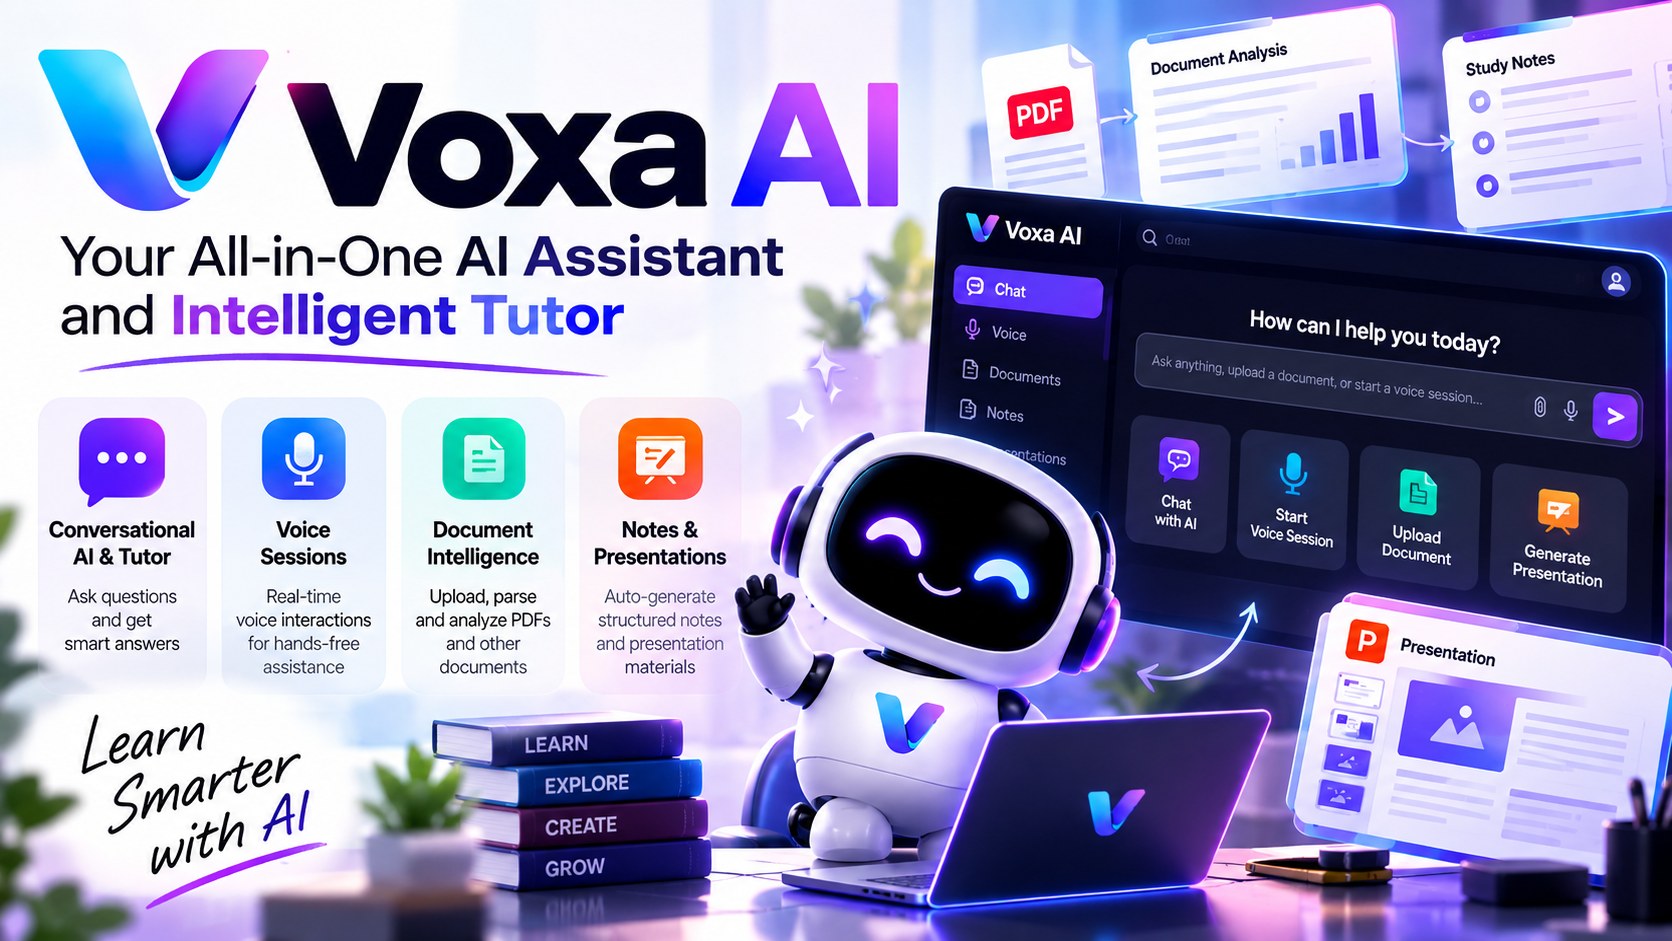
Most "AI tutor" demos are a chat window with a system prompt. Voxa started from a different question: what does a student actually need across a real study session — not just answers to questions, but voice interaction when typing is slower than talking, document understanding when the material is a 40-page PDF, and something to walk away with when the session's over?
That's the shape Voxa ended up taking: a multimodal tutoring platform combining conversational chat, real-time voice sessions, document intelligence, and auto-generated study material, built on a Next.js frontend and FastAPI backend.
A chat-only tutor works fine for quick factual questions. It breaks down the moment a student wants to discuss something out loud while looking at their notes, or needs the assistant to actually read and reason over a document instead of them pasting fragments into a text box. Voxa's three input modes exist because each one covers a real gap the others leave:
The part that separates Voxa from a chatbot wrapper is what happens after the conversation: sessions can be turned into structured notes and presentation material automatically, so a study session produces something reusable instead of disappearing into scrollback the moment the tab closes.
The hard part wasn't building voice, chat, and document parsing individually — each is a solved problem with existing tooling. It was making them feel like one assistant with continuous context, so a student can ask a question in text, get an answer that references a document they uploaded earlier, and switch to voice mid-session without losing that context. That required a shared conversation-state layer underneath all three input modes rather than treating them as separate features that happen to share a UI.
Next.js on the frontend for the real-time UI, FastAPI on the backend handling the document processing and orchestration layer, with Python powering the document intelligence and notes-generation pipeline.
FAQ
It combines three input modes — text chat, real-time voice, and document intelligence — with shared conversational context across all three, plus auto-generated notes and presentation material from a session.