
Loading…
11 September 2026
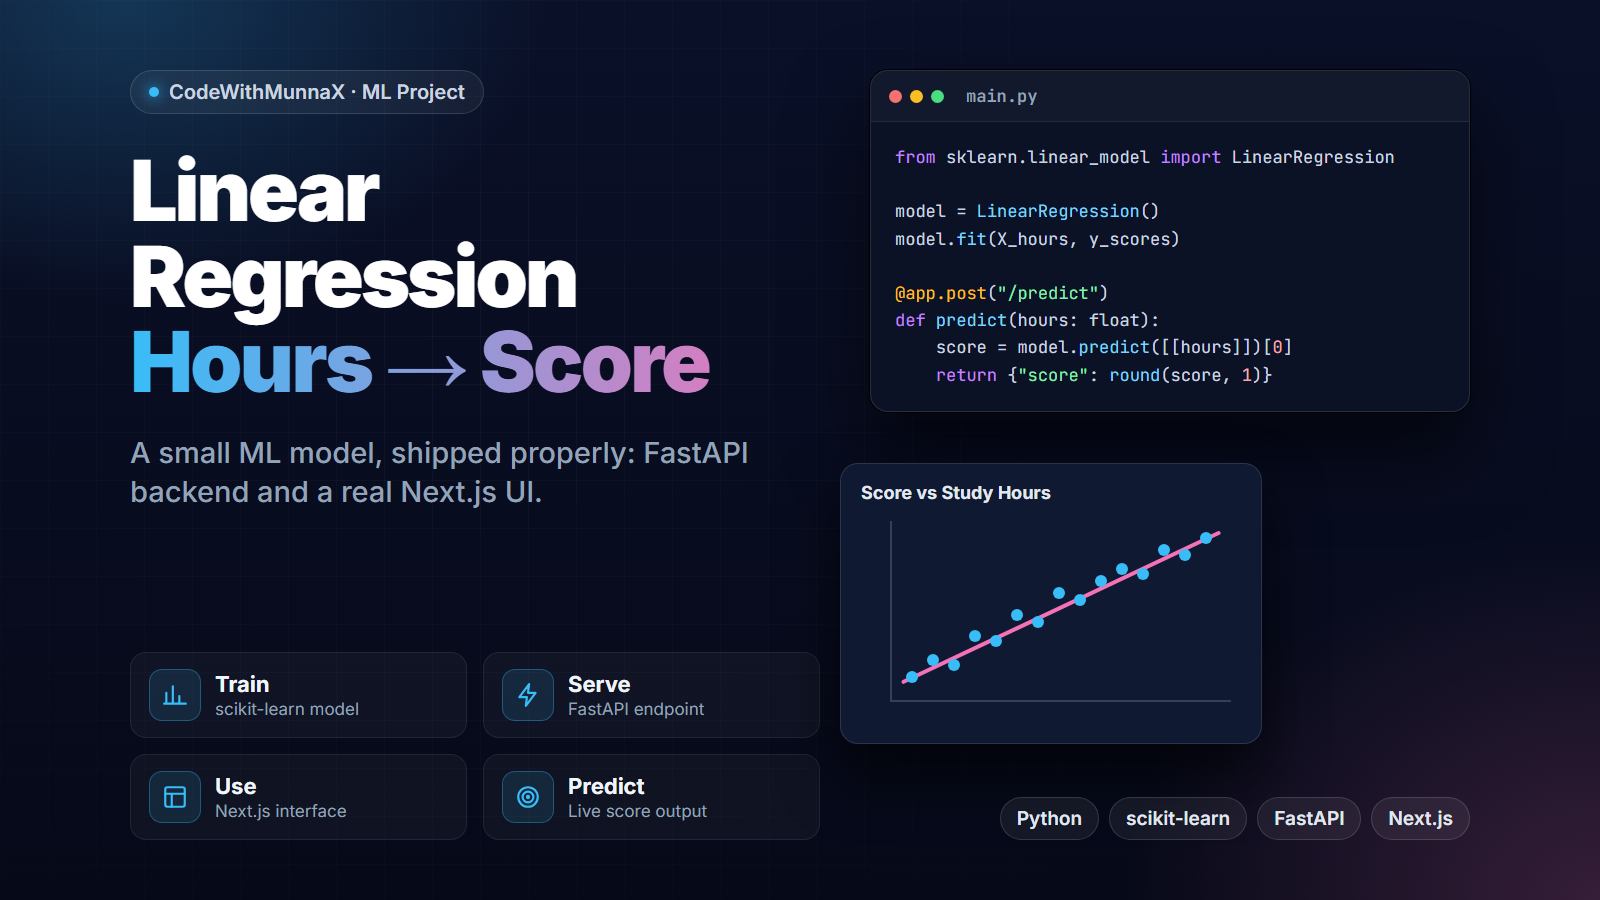
Not every machine learning project needs to be complex to be worth building properly. This one is intentionally simple on the modeling side — predict a student's test score from their study hours using linear regression — and the actual engineering effort went into making it a real, usable application instead of a notebook that ends at model.predict().
A straightforward scikit-learn linear regression trained on study-hours-to-score data. There's no attempt to dress this up as more sophisticated than it is — the point of this project isn't algorithmic complexity, it's demonstrating the full path from a trained model to something an actual user can open and use.
A Jupyter notebook that ends with a prediction printed to a cell is a common stopping point for ML tutorials, and it's also where most of the actual product-building skill gets skipped. Turning that into something usable meant:
.predict() in-processprint() statementThe model training here is genuinely simple. What separates this from a tutorial exercise is everything around it: a versioned API contract between frontend and backend, input validation on the FastAPI side (rejecting nonsensical inputs like negative study hours), and a frontend that treats the prediction as a real feature rather than a demo of an API call working.
A lot of ML portfolios are top-heavy — a few genuinely complex projects and a pile of notebooks that never became anything a non-technical person could open. This project is deliberately on the simple end of the complexity spectrum, built specifically to demonstrate that the "wrap it in a real app" step isn't optional polish — it's the difference between a model and a product, even when the model itself is basic.
FAQ
No, intentionally not — it's a straightforward scikit-learn linear regression. The point of the project is the full pipeline from trained model to usable app, not modeling sophistication.