
Loading…
11 September 2026
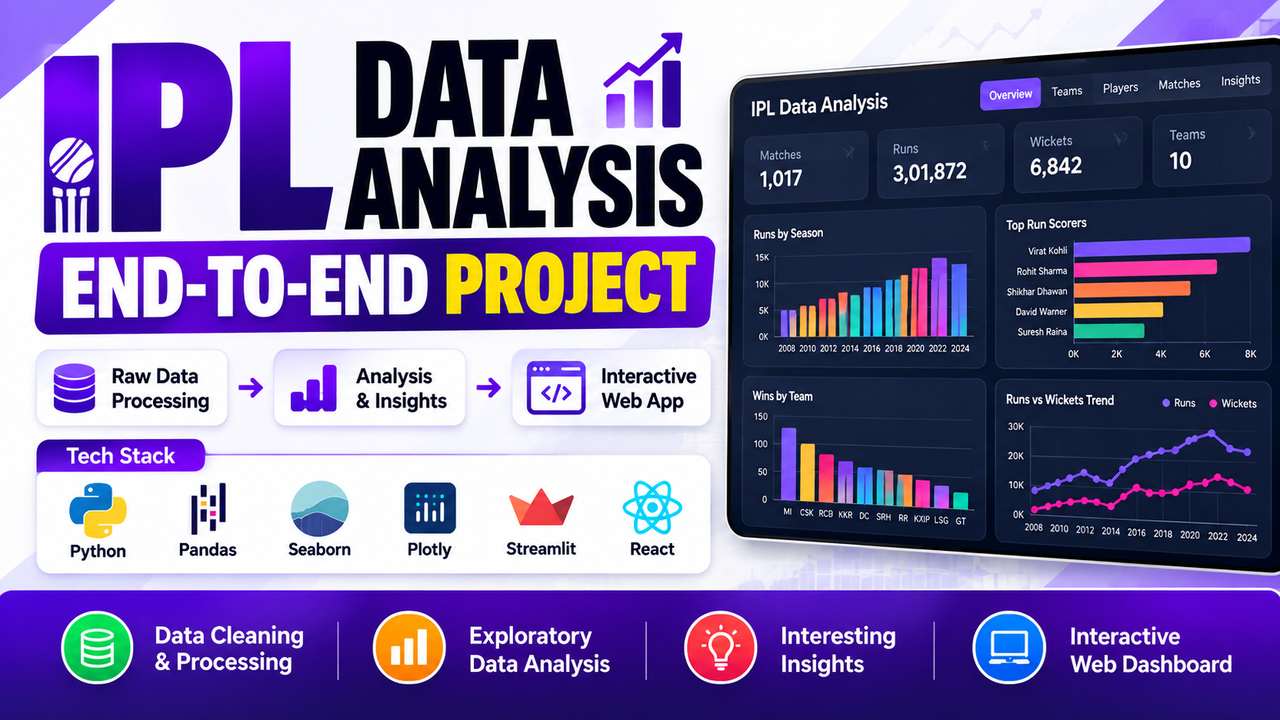
Raw IPL match data — ball-by-ball logs, scorecards, player stats across seasons — is exactly the kind of dataset that tempts you into dumping every possible chart onto a page and calling it a dashboard. This project is deliberately not that: the goal was structured, decision-ready insight, which means most of the actual work happened before a single chart got rendered.
IPL data spanning multiple seasons is inconsistent in ways real datasets always are — team names change (franchise rebrands), player names have spelling variants across seasons, match formats shifted slightly over the years. None of that is visible in a finished dashboard, and all of it has to be resolved before the data can be aggregated correctly. This is the Python side of the stack: cleaning, normalizing, and aggregating raw match data into a shape that's actually queryable.
A chart dump answers "what happened." A decision-ready dashboard is built around specific questions someone would actually want answered — which teams perform better chasing versus defending, how a specific player's form trends across a season, which grounds favor batting versus bowling — and structures the data and visualizations around those questions rather than rendering every column in the dataset as its own chart.
The frontend, in TypeScript, is where the "structured" part becomes visible — filterable views by season, team, and player, rather than one static page. That interactivity is what turns a report into a dashboard: the same underlying aggregated data supports multiple angles of inquiry instead of one fixed narrative.
Data analytics work in the real world is disproportionately about the data preparation, not the final chart — cleaning, joining, and structuring messy real-world data correctly is what determines whether the insight at the end is trustworthy. This project is built specifically to demonstrate that pipeline, not just the visualization layer at the end of it.
FAQ
The data cleaning and normalization work — resolving inconsistent team/player names and formats across seasons — happens before any chart is built, and the dashboard is structured around specific analytical questions rather than a chart-per-column dump.